요약 / TL;DR
Helion을 vLLM의 선형 백엔드(linear backend)에 통합했습니다. 자동 튜닝(autotuning)되는 고수준 커널 DSL이 커널 구현의 복잡도를 줄이면서 LLM 추론 성능을 어떻게 높일 수 있는지 살펴보기 위해서입니다. Helion으로 작성한 일반 행렬 곱셈(GEMM, general matrix multiplication) 구현 하나가 Standard GEMM, Split-K, Swap-AB 같은 여러 알고리즘 변형을 모두 다룰 수 있습니다. 가장 좋은 변형과 구성(config)은 입력 형태(shape)별 자동 튜닝으로 선택됩니다.
We integrated Helion into vLLM’s linear backend to explore how an autotuned, high-level kernel DSL can improve LLM inference performance while reducing kernel implementation complexity. A single Helion general matrix multiplication (GEMM) implementation can cover multiple algorithmic variants, including Standard GEMM, Split-K, and Swap-AB, with the best variant and config automatically selected through per-shape autotuning.
NVIDIA Hopper GPU에서 Helion 선형 백엔드는 형태별 튜닝과 하이브리드 디스패치(hybrid dispatch)를 결합해, 평가한 모델 전반에서 vLLM 기본 백엔드인 CUTLASS와 DeepGEMM보다 좋은 성능을 냈습니다. 엔드투엔드(end-to-end) 성능이 일관되게 향상되었고, 일부 워크로드에서는 처리량(throughput)이 10% 넘게 개선되었습니다.
On NVIDIA Hopper GPUs, the Helion linear backend combines per-shape tuning with hybrid dispatch to outperform the vLLM default CUTLASS and DeepGEMM backends across the evaluated models, delivering consistent end-to-end performance gains and more than 10% throughput improvement for some workloads.
vLLM과 Helion에 대한 간략한 배경 / Brief Background on vLLM and Helion
vLLM은 대규모 언어 모델(LLM)을 위한 고성능 추론 및 서빙 프레임워크입니다. vLLM은 FP8, INT8, INT4, NVFP4 같은 양자화(quantized) 선형 계층을 위해 특화된 선형 백엔드를 제공합니다. 이 백엔드들은 CUTLASS, DeepGEMM, FlashInfer 같은 라이브러리의 하드웨어 최적화 커널 구현을 통합합니다. 덕분에 vLLM은 양자화 형식과 하드웨어 플랫폼마다 최적화된 커널을 쓸 수 있습니다.
vLLM is a high-performance inference and serving framework for large language models (LLMs). For quantized linear layers, such as FP8, INT8, INT4, and NVFP4, vLLM provides specialized linear backends that integrate hardware-optimized kernel implementations from libraries such as CUTLASS, DeepGEMM, and FlashInfer. These backends allow vLLM to use optimized kernels for different quantization formats and hardware platforms.
Helion은 타일 프로그래밍(tile-programming) 모델로 고성능 커널을 작성하도록 설계된, PyTorch 네이티브이면서 하드웨어에 구애받지 않는 커널 DSL입니다. 고수준 추상화 덕분에 개발자는 간결한 Python 스타일 코드로 커널을 한 번만 작성하고, Helion은 하드웨어 플랫폼과 워크로드마다 특화된 코드를 생성합니다. Helion은 워크로드와 하드웨어 타깃마다 커널을 손으로 특화하는 대신, 사전(AOT, ahead-of-time) 자동 튜너(autotuner)로 넓은 탐색 공간을 체계적으로 탐색해 가장 성능이 좋은 구성을 고릅니다. 이 탐색 공간은 저수준의 메모리 레이아웃과 커널 스케줄링부터 고수준의 알고리즘 선택까지 아우릅니다. 고수준 추상화와 체계적인 자동 튜닝의 조합 덕분에, 커널 구현 하나를 다양한 워크로드와 하드웨어에 맞게 최적화할 수 있습니다. Helion은 튜닝 효율을 더 높이기 위해 LLM 기반 탐색(LLM-guided search)도 지원합니다.
Helion is a PyTorch-native hardware agnostic kernel DSL designed for writing high-performance kernels using a tile-programming model. Its high-level abstraction allows developers to express a kernel once in concise Pythonic code, while Helion generates specialized code for different workloads on different hardware platforms. Rather than manually specializing kernels for each workload and hardware target, Helion relies on ahead-of-time (AOT) autotuner to systematically explore a broad search space, from low-level memory layout and kernel scheduling to high-level algorithmic choices, and select the best-performing config. This combination of high-level abstraction and systematic autotuning enables a single kernel implementation to be optimized across diverse workloads and hardware. Helion also supports LLM-guided search to further improve tuning efficiency.
Helion 도입의 기회와 과제 / Helion Adoption Opportunities and Challenges
이 절에서는 vLLM 같은 추론 엔진에 Helion 커널을 도입할 때의 주요 기회와 과제를 정리합니다. Helion이 주는 가치와 그에 따르는 트레이드오프(tradeoff)를 개괄합니다.
This section summarizes the key opportunities and challenges of adopting Helion kernels in inference engines such as vLLM, providing a high-level overview of Helion’s value proposition and tradeoffs.
기회 / Opportunities
성능(Performance): 이전 작업에서는 Helion이 세밀한(fine-grained) 튜닝으로 다양한 워크로드 패턴과 하드웨어 플랫폼에 걸쳐 추론 커널의 최고 수준(SOTA) 성능을 달성할 잠재력이 있음을 보였습니다.
Performance: Our previous work demonstrated Helion’s potential to achieve SOTA performance for inference kernels across diverse workload patterns and hardware platforms through fine-grained tuning.
체계적인 튜닝 프레임워크(Systematic Tuning Framework): 커널 구현을 반복해서 생성하고, 프로파일링하고, 다듬는 열린 형태의 에이전트(agentic) 방식과 달리, Helion은 커널 튜닝을 잘 정의된 탐색 공간 위의 구조화된 수치 최적화 문제로 정식화합니다. 그래서 튜닝 과정이 더 견고하고 믿을 만해집니다. 탐색을 이끄는 데 프로파일링에 의존하지 않으면서도 튜닝 효율에서는 경쟁력을 유지합니다. 또한 Helion은 LLM 기반 탐색을 지원해, LLM의 추론 능력과 체계적인 수치 최적화를 결합하여 탐색 공간을 효율적으로 탐색합니다.
Systematic Tuning Framework: Compared with more open-ended agentic approaches that iteratively generate, profile, and refine kernel implementations, Helion formulates kernel tuning as a structured numerical optimization problem over a well-defined search space. This makes the tuning process more robust and reliable while remaining competitive in tuning efficiency, without relying on profiling to guide the search. Helion further supports LLM-guided search, combining the reasoning capabilities of LLMs with systematic numerical optimization to efficiently navigate the search space.
이식성과 추상화(Portability and Abstraction): Helion은 단지 이식 가능한 DSL에 그치지 않습니다. 커널 구현 하나만 유지하면서 서로 다른 워크로드 패턴과 하드웨어 플랫폼에 맞게 최적화할 수 있습니다.
Portability and Abstraction: Helion is not only a portable DSL. It is possible to maintain a single kernel implementation while optimizing it for different workload patterns and hardware platforms.
사용자 측 커널 최적화(Client-Side Kernel Optimization): vLLM 같은 추론 엔진의 기본 커널은 보통 일반적인 워크로드와 자주 쓰이는 모델에 맞춰 최적화되어 있습니다. Helion을 쓰면 사용자는 전문적인 커널 지식이나 큰 엔지니어링 노력 없이도 자신의 배포 환경에 맞게 커널 성능을 더 튜닝할 수 있습니다.
Client-Side Kernel Optimization: Default kernels in inference engines such as vLLM are typically optimized for general workloads and commonly used models. With Helion, users can further tune kernel performance for their specific deployments without requiring specialized kernel expertise or significant engineering effort.
과제 / Challenges
Helion을 추론 엔진에 통합하는 데에는 아직 몇 가지 과제가 있습니다. Helion 팀은 이를 해결하고 완화하는 작업을 진행하고 있습니다.
Helion still has some challenges integrating into inference engines, with ongoing work from the Helion team to address and mitigate them.
사전 커널 튜닝 오버헤드(Ahead-of-time kernel tuning overhead): Helion은 커널 튜닝을 자동화하고 체계화하지만, 세밀한 튜닝에는 여전히 몇 시간이 걸릴 수 있습니다. 이 오버헤드는 Helion 자체보다는 주로 튜닝 전략의 세밀함(granularity)에서 옵니다. 다른 커널 DSL로 같은 수준의 워크로드별 특화를 하려 해도 비슷한, 어쩌면 더 큰 튜닝 비용이 들 것입니다.
Ahead-of-time kernel tuning overhead: Helion automates and systematizes kernel tuning, but fine-grained tuning can still take hours. This overhead comes primarily from the granularity of the tuning strategy rather than from Helion itself. Achieving the same level of workload-specific specialization with other kernel DSLs would incur comparable—or potentially greater—tuning costs.
시작 시간 오버헤드(Startup-time overhead): vLLM이 시작할 때 수행하는 CUDA 그래프(CUDA Graph) 캡처가 Helion JIT 컴파일을 유발해 콜드 스타트(cold-start) 지연 시간이 늘어납니다. 컴파일된 결과물을 캐싱하면 웜 스타트(warm start)에서는 이 오버헤드를 대부분 없앨 수 있습니다.
Startup-time overhead: CUDA Graph capture during vLLM startup triggers Helion JIT compilation, increasing cold-start latency. This overhead can be largely eliminated on warm starts by caching compiled artifacts.
추론 실행 시간 오버헤드(Inference-runtime overhead): CUDA 그래프 캡처 범위 밖에서는 추론 중 Helion 커널의 디스패치와 호출(launch)이 CPU 오버헤드를 더할 수 있습니다. 이 오버헤드는 세밀한 튜닝으로 얻은 성능 이득을 상쇄할 수 있습니다. 실제로 Helion은 이 CPU 오버헤드를 피할 수 있도록 CUDA 그래프 아래에서 실행할 때 가장 효과적입니다.
Inference-runtime overhead: Outside the CUDA Graph capture range, Helion kernel dispatch and launch during inference can introduce additional CPU overhead, potentially offsetting the performance gains from fine-grained tuning. In practice, Helion is most effective when executed under CUDA Graphs to avoid this CPU overhead.
유지 관리 오버헤드(Maintenance overhead): 인기 모델을 위해 미리 튜닝한 구성을 함께 배포하면 업스트림(upstream)에 지속적인 유지 관리 부담이 생깁니다. 큰 구성 파일은 유지 관리하기 어렵고, 단위 테스트와 CI로 빠짐없이 검증하기도 현실적이지 않습니다.
Maintenance overhead: Shipping pre-tuned configs for popular models creates an ongoing upstream maintenance burden. Large config files are difficult to maintain and impractical to validate exhaustively through unit tests and CI.
트레이드오프 삼각형 / The Tradeoff Triangle
Helion으로 커널을 세밀하게 튜닝하면 성능(performance), 사용성(usability), 유지 관리성(maintainability) 사이에 트레이드오프가 생깁니다. 이 트레이드오프는 Helion만의 문제가 아니라 워크로드별 커널 최적화에 본질적으로 따르는 것입니다. 둘을 최적화하면 대개 나머지 하나를 희생하게 됩니다.
Fine-grained kernel tuning with Helion presents a tradeoff among performance, usability, and maintainability. This tradeoff is not specific to Helion, but is inherent to workload-specific kernel optimization: optimizing for two often comes at the expense of the third.
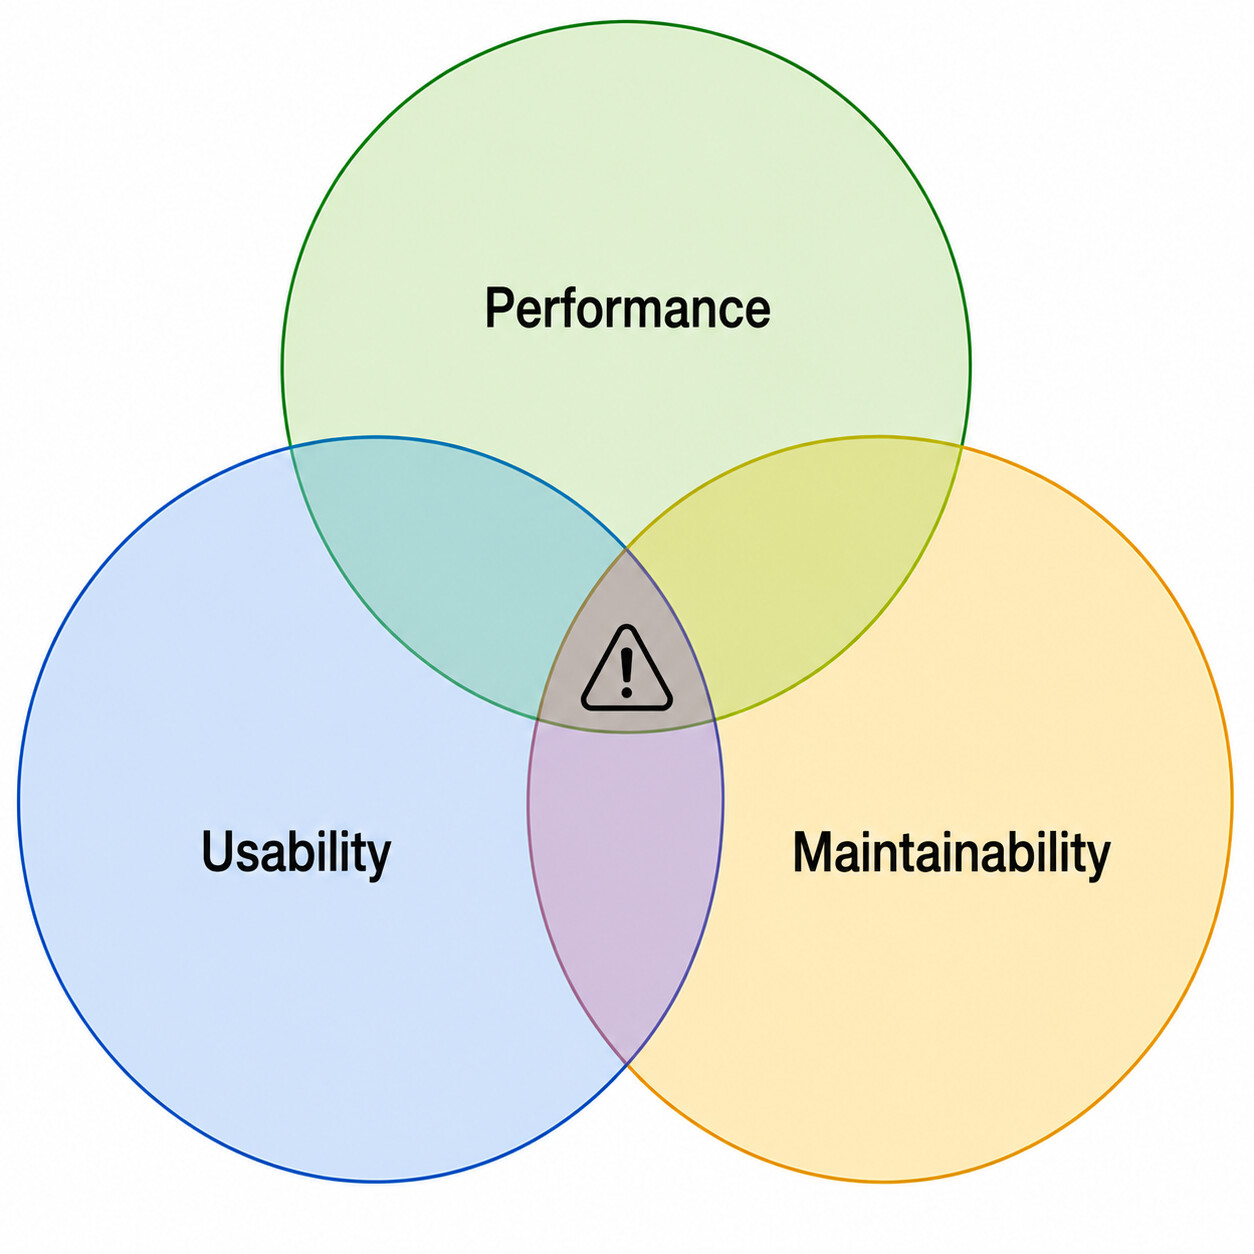
그림 1: 성능-사용성-유지 관리성 트레이드오프 삼각형 / Fig. 1: The Performance-Usability-Maintainability tradeoff triangle
성능을 높이려면 대체로 구성을 더 세밀하게 튜닝해야 합니다. 그러면 사용자 측의 자동 튜닝 오버헤드가 늘어나거나, 유지 관리자가 업스트림에서 미리 튜닝한 구성을 더 많이 제공하고 관리해야 합니다. 따라서 목표는 대상 사용 사례에 맞는 적절한 균형을 찾는 것입니다.
Higher performance generally requires more fine-grained config tuning. This either increases client-side autotuning overhead or requires maintainers to provide and maintain more pre-tuned configs upstream. The goal, therefore, is to strike the right balance for the target use case.
Helion 선형 백엔드 / Helion Linear Backend
범위 / Scope
이번 작업에서는 vLLM에 Helion 선형 백엔드를 추가했으며, Helion의 Triton 백엔드를 사용해 NVIDIA Hopper GPU에 집중했습니다. Hopper에서 효율적인 추론을 위한 주요 양자화 형식은 FP8과 INT8이므로, 다음 형식의 양자화 GEMM을 대상으로 합니다:
- FP8_Dynamic: FP8, 활성화는 토큰별(per-token), 가중치는 채널별(per-channel) 스케일링.
- W8A8_INT8: INT8, 활성화는 토큰별, 가중치는 채널별 스케일링.
- Block_FP8: FP8, 활성화는 1×128, 가중치는 128×128 단위 스케일링.
This work adds a Helion linear backend to vLLM and focuses on NVIDIA Hopper GPUs using Helion’s Triton backend. FP8 and INT8 are the primary quantization formats for efficient inference on Hopper, so we target quantized GEMM with the following formats:
- FP8_Dynamic: FP8 per-token activation and per-channel weight scaling.
- W8A8_INT8: INT8 per-token activation and per-channel weight scaling.
- Block_FP8: FP8 with 1×128 activation scaling and 128×128 weight scaling.
Helion의 CuteDSL 백엔드로 얻은 초기 결과는 NVIDIA Blackwell GPU에서 경쟁력 있는 GEMM 성능을 보여 줍니다. CuteDSL 백엔드가 성숙해지면 이번 작업을 Blackwell 지원으로 확장할 수 있습니다.
Initial results with Helion’s CuteDSL backend show competitive GEMM performance on NVIDIA Blackwell GPUs. As the CuteDSL backend matures, this work can be extended to support Blackwell.
커널 구현 / Kernel Implementation
특정 입력 형태에서 성능을 높일 수 있는 GEMM 알고리즘 변형이 여러 가지 있습니다. 특히 다음과 같습니다:
- Split-K: M 차원이나 N 차원(또는 둘 다)이 너무 작을 때, K 차원을 여러 스레드 블록에 나눠 병렬성을 높입니다.
- Swap-AB: A@B를 ([email protected]).T로 바꿔 씁니다. M 차원이 작은 형태에서 더 유리한 타일링과 더 나은 GPU 활용을 가능하게 해 성능을 높입니다.
Several GEMM algorithm variants can improve performance for specific input shapes. In particular:
- Split-K: Partitions the K dimension across multiple thread blocks to increase parallelism when the M and/or N dimensions are too small.
- Swap-AB: Rewrites A@B as ([email protected]).T to improve performance for shapes with a small M dimension by enabling more favorable tiling and better GPU utilization.
전통적으로 커널 작성자는 여러 GEMM 변형을 구현하고, 표준 GEMM과 이 특화 변형들을 벤치마크하고, 입력 형태에 따라 어느 구현으로 디스패치할지 정하는 휴리스틱(heuristic)을 만들어야 합니다. 예를 들어 현재 vLLM의 Block_FP8 선형 백엔드는 Hopper에서 M < 32이면 Swap-AB 변형으로 디스패치합니다. 이런 휴리스틱은 보통 전반적으로 잘 동작하도록 설계되지만, 모든 모델이나 워크로드에서 최적은 아닐 수 있습니다.
Traditionally, kernel authors need to implement multiple GEMM variants, benchmark the standard GEMM against these specialized variants, and develop heuristics to determine which implementation to dispatch to based on the input shape. For example, vLLM’s current Block_FP8 linear backend dispatches to the Swap-AB variant when M < 32 on Hopper. Such heuristics are typically designed to perform well in general, but may not be optimal for every model or workload.
Helion을 쓰면 하나로 통합된 GEMM 구현이 Standard, Split-K, Swap-AB 세 변형을 모두 다룰 수 있습니다. 커널을 따로 구현하고 디스패치 휴리스틱을 손으로 설계하는 대신, 알고리즘 선택을 튜닝 가능한 매개변수로 노출합니다. 그러면 AOT 자동 튜너가 워크로드마다 가장 좋은 변형과 저수준 커널 구성을 함께 자동으로 고를 수 있습니다.
With Helion, a single unified GEMM implementation can cover all three variants—Standard, Split-K, and Swap-AB. Instead of implementing separate kernels and manually designing dispatch heuristics, the algorithmic choices are exposed as tunable parameters. The AOT autotuner can then automatically select the best variant along with the low-level kernel config for each workload.
간단히 설명하기 위해 아래에서는 기본적인 행렬 곱셈 커널로 이 접근 방식을 보여 줍니다. 이번 작업에서 쓴 양자화 GEMM 커널도 같은 구조를 따르며, 양자화와 스케일링 로직이 더해집니다.
For simplicity, we use a basic matrix multiplication kernel below to illustrate the approach. The quantized GEMM kernels used in this work follow the same structure, with additional quantization and scaling logic.
def matmul(
    out: torch.Tensor,  # [M, N]
    a: torch.Tensor,    # [M, K]
    b: torch.Tensor,    # [K, N]
) -> None:
    M, K = a.shape
    N = b.shape[1]
    hl.specialize(K)
    hl.specialize(N)
    out_dtype = out.dtype
    acc_dtype = torch.float32
    split_k = hl.register_tunable(
        "split_k", PowerOfTwoFragment(1, 256)
    )
    k_block_size = helion.next_power_of_2(helion.cdiv(K, split_k))
    if split_k > 1:
        out.zero_()
    swap_ab = hl.register_tunable(
        "swap_ab", BooleanFragment()
    )
    for tile_m, tile_n, outer_k in hl.tile(
        [M, N, K],
        block_size=[None, None, k_block_size]
    ):
        acc = hl.zeros([tile_m, tile_n], acc_dtype)
        acc_t = acc.t()
        for tile_k in hl.tile(outer_k.begin, outer_k.end):
            if swap_ab:
                a_blk = hl.load(a, [tile_m.index[None, :], tile_k.index[:, None]])
                b_blk = hl.load(b, [tile_k.index[None, :], tile_n.index[:, None]])
                acc_t = hl.dot(
                    b_blk,
                    a_blk,
                    acc=acc_t,
                    out_dtype=acc_dtype,
                )
            else:
                acc = hl.dot(
                    a[tile_m, tile_k],
                    b[tile_k, tile_n],
                    acc=acc,
                    out_dtype=acc_dtype,
                )
        if swap_ab:
            out_blk = acc_t.t().to(out_dtype)
        else:
            out_blk = acc.to(out_dtype)
        if split_k == 1:
            out[tile_m, tile_n] = out_blk
        else:
            hl.atomic_add(out, [tile_m, tile_n], out_blk)
이 구현은 두 알고리즘 선택을 모두 튜닝 가능한 매개변수로 노출합니다. split_k 는 256 이하의 2의 거듭제곱 값으로 제한되고, swap_ab 는 불리언(Boolean) 매개변수입니다. 자동 튜너는 이렇게 제한된 탐색 공간을 탐색하면서 여러 조합을 벤치마크하고, 워크로드마다 가장 좋은 변형을 고릅니다.
This implementation exposes both algorithmic choices as tunable parameters:
split_kis constrained to power-of-two values up to 256, whileswap_abis a Boolean parameter. The autotuner explores the constrained search space, benchmarks different combinations, and selects the best variant for each workload.
하이브리드 디스패치 / Hybrid Dispatch
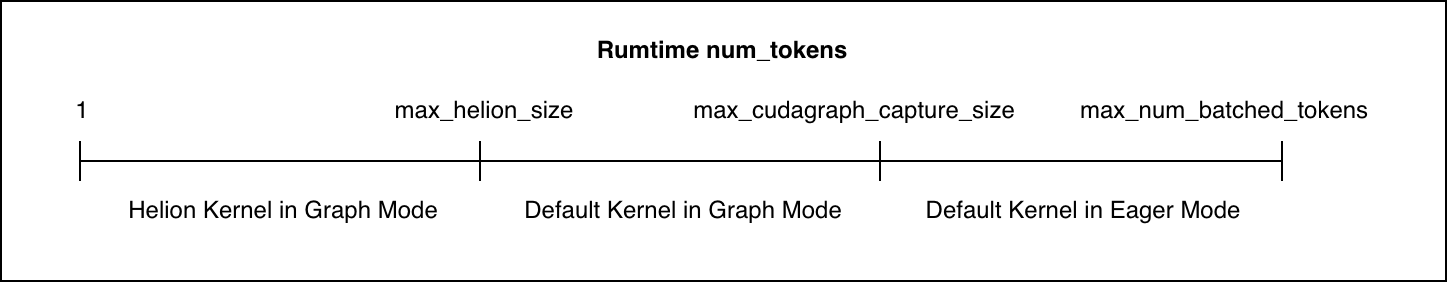
그림 2: 실행 시점의 num_tokens와 CUDA 그래프 적용 범위에 따른 Helion 선형 백엔드의 하이브리드 디스패치 전략 / Fig. 2: Helion linear backend hybrid dispatch strategy based on runtime num_tokens and CUDA Graph coverage.
실행 시점의 num_tokens 와 CUDA 그래프 적용 범위에 따라 동작하는 하이브리드 디스패치 전략을 채택했습니다. max_helion_size 이하의 작은 형태에서는 선형 백엔드가 CUDA 그래프 재생(replay) 아래에서 Helion으로 디스패치합니다. max_helion_size 를 넘는 큰 형태에서는 기본 커널(CUTLASS/DeepGEMM)로 대체(fall back)합니다.
We adopt a hybrid dispatch strategy based on runtime
num_tokensand CUDA Graph coverage. For small shapes up tomax_helion_size, the linear backend dispatches to Helion under CUDA Graph replay. For larger shapes beyondmax_helion_size, it falls back to the default kernel (CUTLASS/DeepGEMM).
이 하이브리드 디스패치 전략에는 세 가지 실용적인 이점이 있습니다:
- Helion의 실행 시간 오버헤드를 없앱니다. Helion 커널은 CUDA 그래프 재생으로만 실행되므로, 커널 디스패치와 호출에서 오는 추가 CPU 오버헤드를 피합니다.
-
커널 튜닝 오버헤드를 줄입니다. 세밀한 Helion 튜닝을 디코딩 워크로드의 대부분을 차지하는 작은
num_tokens범위로 제한합니다. 그래서 튜닝해야 하는 입력 형태의 수가 크게 줄어들면서도, 의미 있는 엔드투엔드 성능 향상의 여지는 그대로 남습니다. - 구성 유지 관리 오버헤드를 줄입니다. 튜닝한 구성의 수가 적어서, 미리 튜닝한 구성을 검증하고 배포하고 오래 유지 관리하기가 더 현실적입니다.
This hybrid dispatch strategy provides three practical benefits:
- Eliminates Helion runtime overhead. Helion kernels execute only through CUDA Graph replay, avoiding the additional CPU overhead from kernel dispatch and launch.
- Reduces kernel tuning overhead. Fine-grained Helion tuning is limited to the small
num_tokensrange that dominates decoding workloads, significantly reducing the number of input shapes that need to be tuned while preserving the opportunity for meaningful end-to-end performance gains.- Reduces config maintenance overhead. The smaller set of tuned configs makes pre-tuned configs more practical to validate, ship, and maintain over time.
커널 자동 튜닝 / Kernel Autotuning
vLLM에 있는 유틸리티 스크립트로 Helion 선형 커널을 자동 튜닝합니다:
We autotune the Helion linear kernels using the utility script available in vLLM:
HELION_AUTOTUNER=LLMSeededLFBOTreeSearch \
HELION_BENCHMARK_CUDAGRAPH =1 \
python scripts/autotune_helion_kernels.py \
  --kernels scaled_mm block_scaled_mm \
  --autotune-effort "full"
역주: 원문 명령의 HELION_BENCHMARK_CUDAGRAPH =1 에는 = 앞에 공백이 있습니다. 셸에서 환경 변수로 지정하려면 공백 없이 HELION_BENCHMARK_CUDAGRAPH=1 로 써야 합니다.
아래 절에서는 이번 작업에서 사용한 주요 튜닝 전략과 설정을 설명합니다.
형태별 구성 튜닝 / Per-shape Config TuningThe following sections describe the key tuning strategies and setups used in this work.
CUTLASS, DeepGEMM, FlashInfer처럼 고도로 최적화된 GEMM 라이브러리와 경쟁하기 위해, Helion 디스패치 범위 안의 입력 형태마다 Helion 커널을 개별적으로 튜닝합니다.
To compete with highly optimized GEMM libraries such as CUTLASS, DeepGEMM, and FlashInfer, we tune the Helion kernel individually for each input shape within the Helion dispatch range.
하이브리드 디스패치 전략에서 설명한 대로, 이번 작업에서는 max_helion_size = 32 로 설정했습니다. vLLM은 다음 num_tokens 값에 대해 CUDA 그래프를 캡처합니다:
As described in the hybrid dispatch strategy, we set
max_helion_size = 32for this work. vLLM captures CUDA Graphs for the following num_tokens values:
[1, 2, 4] + range(8, 256, 8) + range(256, max_graph_size + 1, 16)
따라서 max_helion_size = 32 일 때 Helion 커널은 다음 값에 대해 자동 튜닝됩니다:
With
max_helion_size = 32, the Helion kernels are therefore autotuned for:
num_tokens = [1, 2, 4, 8, 16, 24, 32]
각 num_tokens 값은 모델이 사용하는 해당 GEMM 형태에 대해 개별적으로 튜닝됩니다.
자동 튜너 벤치마킹에 CUDA 그래프 사용 / Enable CUDA Graph for Autotuner BenchmarkingEach num_tokens value is tuned individually for the corresponding GEMM shapes used by the model.
커널 디스패치와 호출에서 오는 추가 CPU 오버헤드 때문에, Helion 커널은 CUDA 그래프 실행 아래에서만 사용합니다. 따라서 CUDA 그래프를 켜고 벤치마크하면, 자동 튜너가 실제 추론 실행과 더 가까운 조건에서 구성을 평가할 수 있습니다.
Due to the additional CPU overhead from kernel dispatch and launch, Helion kernels are used only under CUDA Graph execution. Benchmarking with CUDA Graph enabled therefore allows the autotuner to evaluate configs under conditions that more closely match actual inference execution.
Helion은 이 기능을 HELION_BENCHMARK_CUDAGRAPH 환경 변수로 제공하며, 이번 작업에서는 이 기능을 켰습니다.
LLM 기반 탐색 사용 / Use LLM-Guided SearchHelion exposes this feature through the
HELION_BENCHMARK_CUDAGRAPHenvironment variable and is turned on for this work.
이번 작업의 커널 구성은 LLMSeededLFBOTreeSearch 자동 튜너로 생성했습니다. 이 자동 튜너는 LLM으로 유망한 구성 후보 집합을 찾고, 이를 뒤이은 LFBOTreeSearch의 시드(seed)로 씁니다. 이번 작업에서는 Claude Opus 4.8을 사용했습니다.
The kernel configs in this work are generated using the LLMSeededLFBOTreeSearch autotuner, which uses an LLM to identify a set of promising config candidates as seeds for the subsequent LFBOTreeSearch. For this work, we use Claude Opus 4.8.
더 질 좋은 후보에서 탐색을 시작하면 자동 튜너가 더 성능 좋은 구성을 찾기 쉬워집니다. 또한 탐색 공간에서 더 유망한 영역으로 탐색을 이끌어 전체 자동 튜닝 시간을 줄일 수도 있습니다.
Starting the search from higher-quality candidates helps the autotuner discover better-performing configs. It may also reduce overall autotuning time by directing the search toward more promising regions of the search space.
성능 평가 / Performance Evaluation
여러 밀집(dense) 모델과 양자화 형식에 걸쳐, 커널 수준과 엔드투엔드 서빙 수준 모두에서 Helion 선형 백엔드를 평가했습니다. 모델 크기에 따라 성능이 어떻게 달라지는지 보기 위해 Qwen3-1.7B, Qwen3-4B, Qwen3-8B, Qwen3-14B, Qwen3-32B를 벤치마크했습니다. 더 최근의 모델 아키텍처에서도 백엔드를 평가하기 위해 최신 Qwen3.8-27B 모델도 포함했습니다.
We evaluate the Helion linear backend at both the kernel and end-to-end serving levels across a range of dense models and quantization formats. To understand how performance scales with model size, we benchmark Qwen3-1.7B, Qwen3-4B, Qwen3-8B, Qwen3-14B, and Qwen3-32B. We additionally include the latest Qwen3.8-27B model to evaluate the backend on a more recent model architecture.
각 모델마다 NVIDIA Hopper GPU에서 자주 쓰이는 8비트 양자화 형식 세 가지를 평가합니다. 예를 들어 Qwen3.8-27B는 다음을 벤치마크합니다:
For each model, we evaluate three commonly used 8-bit quantization formats on NVIDIA Hopper GPUs. For example, for Qwen3.8-27B, we benchmark:
모든 벤치마크는 NVIDIA H100 80GB HBM3 GPU에서 수행했습니다.
All benchmarks are performed on an NVIDIA H100 80GB HBM3 GPU.
커널 수준 평가 / Kernel-Level Evaluation
먼저 Helion 양자화 GEMM 커널을 단독으로 평가해, 추론 스택의 나머지 부분과 무관하게 세밀한 튜닝이 주는 성능 이점을 파악했습니다. 각 Helion 커널을 Hopper에서 기본 vLLM 선형 백엔드가 사용하는 해당 커널과 비교합니다:
- FP8_Dynamic: Helion vs. CUTLASS
- W8A8_INT8: Helion vs. CUTLASS
- Block_FP8: Helion vs. FlashInfer/DeepGEMM
We first evaluate the Helion quantized GEMM kernels in isolation to understand the performance benefit of fine-grained tuning independent of the rest of the inference stack. Each Helion kernel is compared against the corresponding kernel used by the default vLLM linear backend on Hopper:
- FP8_Dynamic: Helion vs. CUTLASS
- W8A8_INT8: Helion vs. CUTLASS
- Block_FP8: Helion vs. FlashInfer/DeepGEMM
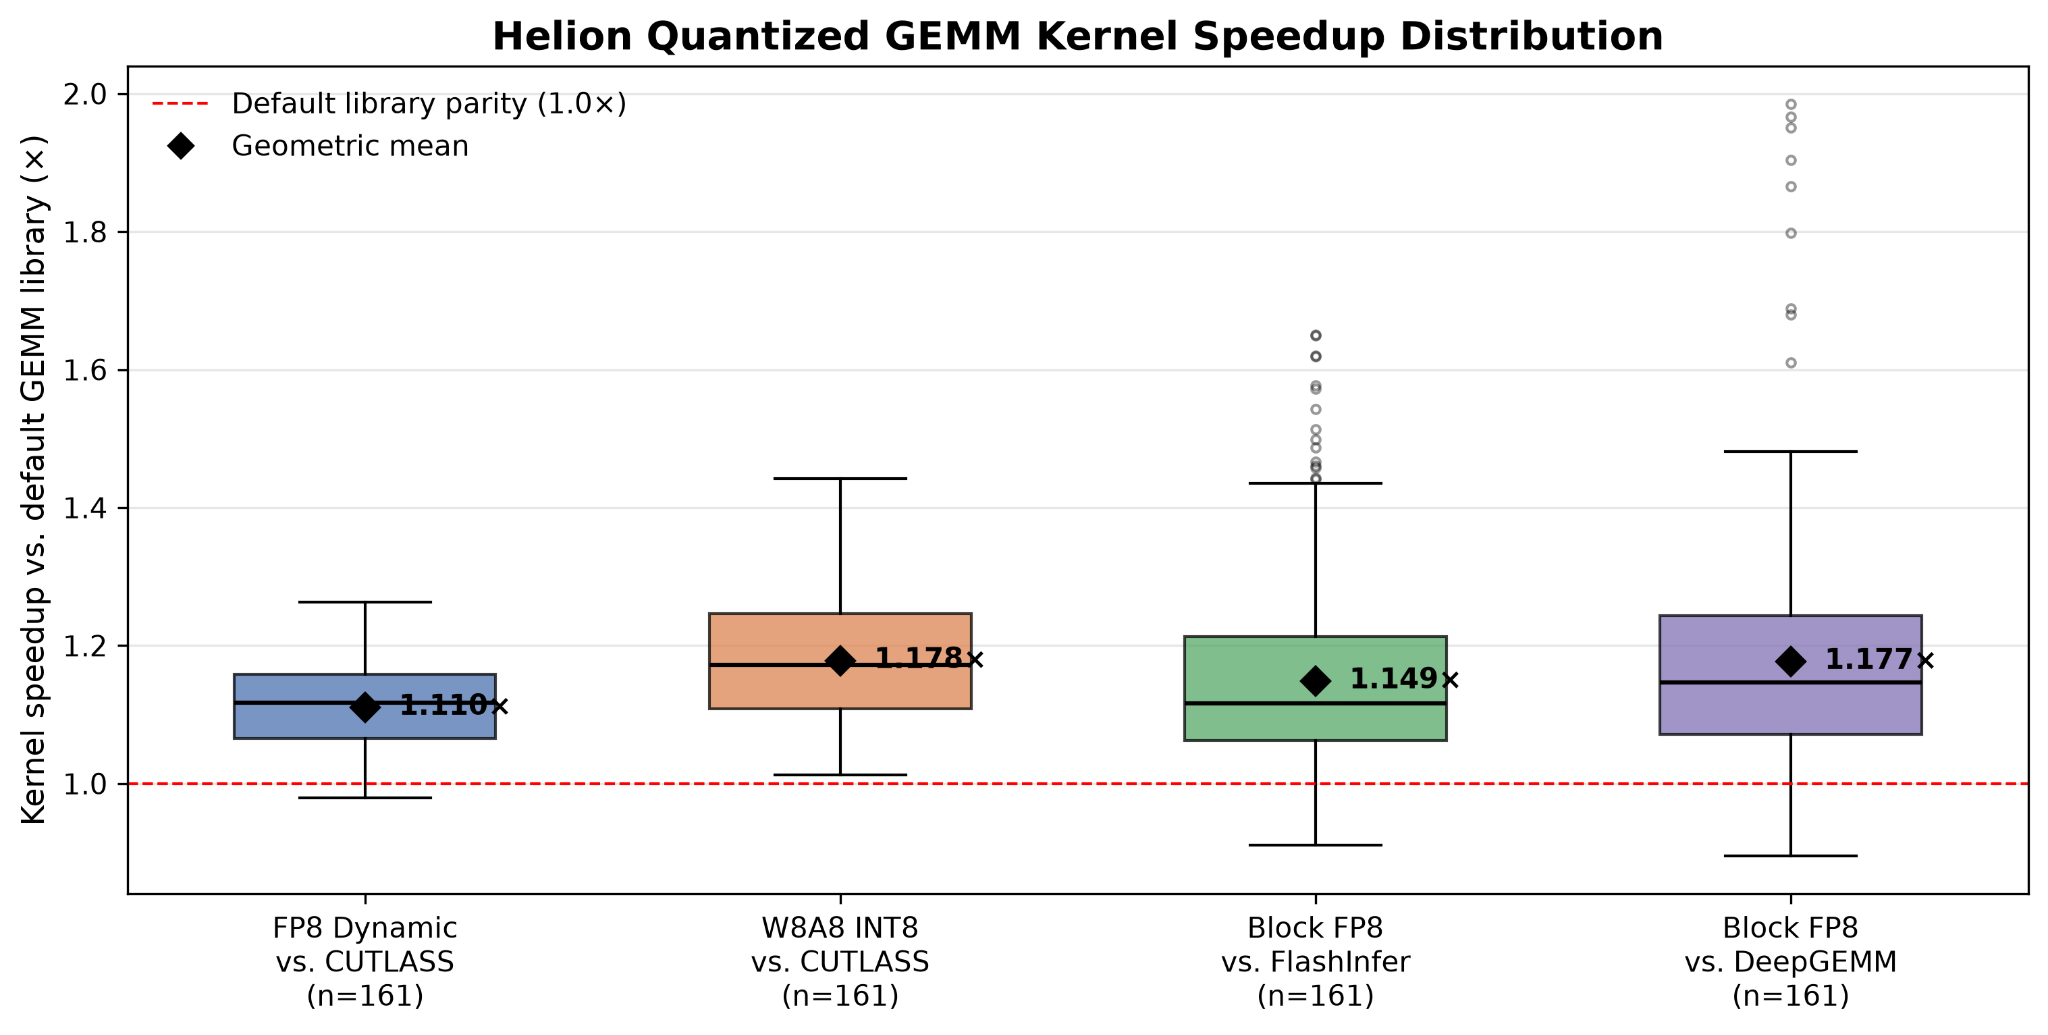
그림 3: 엔드투엔드 벤치마크에 쓴 모델들이 사용하는 모든 입력 형태에서, 기본 vLLM 커널 라이브러리 대비 Helion 양자화 GEMM 커널의 속도 향상 분포. 다이아몬드는 속도 향상의 기하 평균을 나타냅니다. / Fig. 3: Helion quantized GEMM kernel speedup distribution over the default vLLM kernel libraries across all input shapes used by the end-to-end benchmarked models. Diamonds indicate the geometric mean speedup.
Helion은 기하 평균(geometric mean) 기준으로 FP8_Dynamic에서 CUTLASS 대비 1.110배, W8A8_INT8에서 CUTLASS 대비 1.178배, Block_FP8에서 FlashInfer 대비 1.149배, Block_FP8에서 DeepGEMM 대비 1.177배 의 속도 향상을 달성했습니다. 분포를 보면 개별 입력 형태마다 성능이 달라진다는 점도 알 수 있습니다. 이는 커널 구성 하나나 일반적인 디스패치 휴리스틱에 의존하기보다 세밀하게 튜닝하는 것이 가치 있음을 보여 줍니다.
Helion achieves geometric mean speedups of 1.110× for FP8_Dynamic over CUTLASS, 1.178× for W8A8_INT8 over CUTLASS, 1.149× for Block_FP8 over FlashInfer, and 1.177× for Block_FP8 over DeepGEMM. The distribution also shows that performance varies across individual input shapes, highlighting the value of fine-grained tuning rather than relying on a single kernel config or generic dispatch heuristic.
엔드투엔드 평가 / End-to-End Evaluation
다음으로, 커널 수준의 개선이 엔드투엔드 서빙 성능으로 이어지는지 평가했습니다.
서버 설정 / Server SetupWe next evaluate whether the kernel-level improvements translate into end-to-end serving performance.
다음 명령으로 vLLM 서버를 시작합니다:
We use the following command to start the vLLM server:
vllm serve \
    --model "$MODEL" \
    --max-num-seqs 32 \
    --tensor-parallel-size 1 \
    --no-enable-prefix-caching \
    --linear-backend helion
관련 옵션은 다음과 같습니다:
-
--max-num-seqs 32: Helion 선형 백엔드는 현재 하이브리드 디스패치 임곗값으로num_tokens32를 사용합니다. 그래서 Helion 커널이 활성화되어 엔드투엔드 성능에 직접 영향을 줄 수 있는 배치 크기 32 이하에 평가를 집중합니다. -
--no-enable-prefix-caching: 벤치마크 결과에 영향을 주지 않도록 접두사 캐싱(prefix caching)을 의도적으로 끕니다. -
--linear-backend helion: Helion 선형 백엔드를 켭니다. 이 플래그를 빼면 기본 선형 백엔드를 사용합니다.
The relevant options are:
--max-num-seqs 32: The Helion linear backend currently uses a hybrid dispatch threshold of 32num_tokens. We therefore focus the evaluation on batch sizes up to 32, where Helion kernels are active and can directly affect end-to-end performance.--no-enable-prefix-caching: Prefix caching is intentionally disabled to avoid its impact on benchmark results.--linear-backend helion: Enables the Helion linear backend. Omitting this flag uses the default linear backend.
벤치마크 설정 / Benchmark Setup
ShareGPT 데이터셋으로 다음과 같이 엔드투엔드 서빙 벤치마크를 실행합니다:
We run end-to-end serving benchmarks using the ShareGPT dataset with:
vllm bench serve \
    --backend vllm \
    --model "${MODEL}" \
    --endpoint /v1/completions \
    --dataset-name sharegpt \
    --dataset-path "${DATASET}" \
    --max-concurrency "${BATCH_SIZE}" \
    --num-warmups "${NUM_WARMUPS}" \
    --num-prompts "${PROMPTS}" \
    --ignore-eos
각 워크로드는 기본 선형 백엔드와 Helion 선형 백엔드 모두로 벤치마크합니다. Hopper에서 기준선(baseline)으로 쓴 기본 vLLM 선형 백엔드는 다음과 같습니다:
- FP8_Dynamic: CutlassFP8ScaledMMLinearKernel
- W8A8_INT8: CutlassInt8ScaledMMLinearKernel
- Block_FP8: FlashInferFp8DeepGEMMDynamicBlockScaledKernel
엔드투엔드 벤치마크 결과 / End-to-End Benchmark ResultsEach workload is benchmarked with both the default and Helion linear backends. The default vLLM linear backends used as baselines on Hopper are:
- FP8_Dynamic: CutlassFP8ScaledMMLinearKernel
- W8A8_INT8: CutlassInt8ScaledMMLinearKernel
- Block_FP8: FlashInferFp8DeepGEMMDynamicBlockScaledKernel
다음 그림은 모델 크기, 배치 크기, 양자화 형식별로 Helion 선형 백엔드가 해당 기본 백엔드 대비 얻은 엔드투엔드 처리량 속도 향상을 보여 줍니다.
The following Figure shows the end-to-end throughput speedup of the Helion linear backend over the corresponding default backend across different model sizes, batch sizes, and quantization formats.
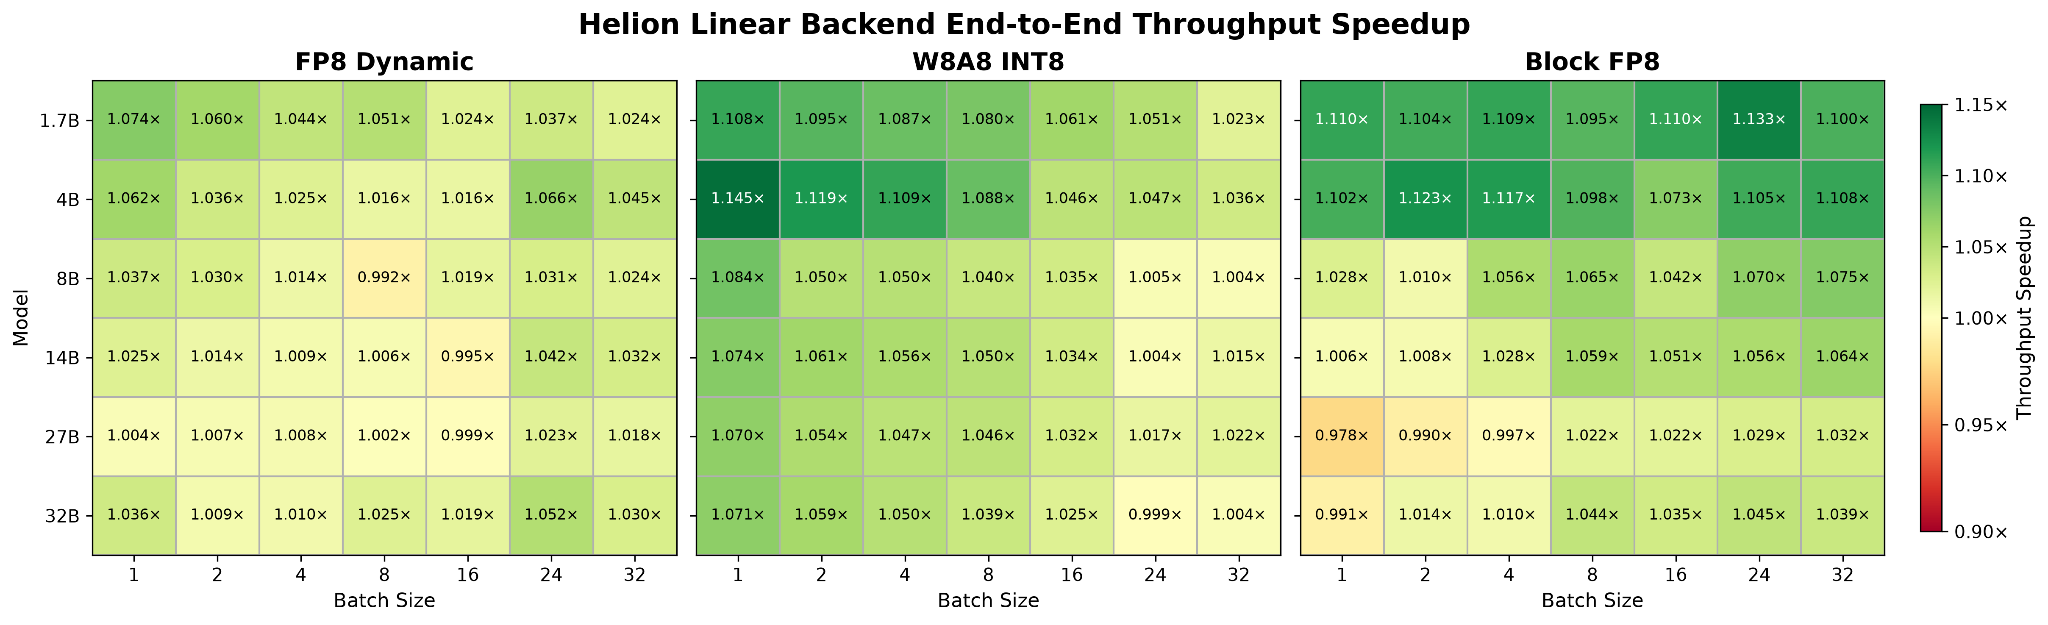
그림 4: Helion 선형 백엔드의 엔드투엔드 처리량 속도 향상 / Fig. 4: Helion linear backend end-to-end throughput speedup.
전반적으로 Helion 선형 백엔드는 평가한 모델과 양자화 형식 전반에서 엔드투엔드 성능을 일관되게 높였고, 일부 워크로드에서는 처리량이 10% 넘게 개선되었습니다.
Overall, the Helion linear backend delivers consistent end-to-end performance gains across the evaluated models and quantization formats, with more than 10% throughput improvement for some workloads.
실용적인 도입 방식을 향하여 / Toward a Practical Adoption Model
이번 글에서 소개한 Helion 선형 백엔드는 현재 vLLM 포크(fork)에서 사용할 수 있으며, 프로덕션에 쓸 수 있는 상태입니다. 이 포크에는 최종 사용자가 다른 모델과 워크로드에 맞는 최적화된 구성을 생성하는 데 필요한 자동 튜닝 도구와 안내도 들어 있습니다. 업스트림 도입에 남은 과제 하나는 미리 튜닝한 대량의 구성을 배포하고 검증하는 유지 관리 오버헤드입니다.
The Helion linear backend presented in this work is currently available in our vLLM fork and ready for production use. The fork also includes the autotuning tooling and instructions needed for end users to generate optimized configs for additional models and workloads. One remaining challenge for upstream adoption is the maintenance overhead of shipping and validating a large collection of pre-tuned configs.
이번 작업에서 다룬 GEMM 커널처럼 지연 시간에 민감한 커널에 대해서는 다음과 같은 운영 방식을 검토하고 있습니다. Helion 커널과 통합 프레임워크는 기능 테스트와 CI용 기본 구성과 함께 업스트림에서 유지 관리하고, 워크로드별 자동 튜닝은 최종 사용자에게 맡기는 방식입니다. 사용자는 이번 작업에서 쓴 것과 같은 자동화 도구로, 배포 전에 대상 모델과 하드웨어에 맞는 최적화된 구성을 생성할 수 있습니다. 이 방식은 바로 쓸 수 있는(out-of-the-box) 사용성보다 성능과 유지 관리성을 우선합니다. 지연 시간에 민감한 커널에서는 성능 이점이 추가적인 오프라인 최적화 노력을 정당화할 수 있으므로, 이 트레이드오프가 현실적이라고 생각합니다. 프로덕션 배포 전에 이런 투자를 할 의향이 있는 모델 서빙 제공자에게는 특히 그렇습니다.
For latency-critical kernels such as the GEMM kernels studied in this work, we are exploring a model in which the Helion kernels and integration framework are maintained upstream with a default config for functional testing and CI, while workload-specific autotuning is delegated to end users. The same automated tooling used in this work allows users to generate optimized configs for their target models and hardware before deployment. This model favors performance and maintainability over out-of-the-box usability. We believe this tradeoff is practical for latency-critical kernels, where the performance benefits can justify the additional offline optimization effort, particularly for model serving providers willing to make this investment before production deployment.
하지만 세밀한 튜닝만이 Helion 커널을 도입하는 유일한 실용적 전략은 아닙니다. 양자화, 활성화, 정규화 커널처럼 더 작은 보조 커널에서는 최고 성능을 어느 정도 포기하는 대신, 여러 형태에 일반화되는 훨씬 작은 구성 집합을 쓰는 편이 나을 수 있습니다. 초기 실험에서는 구성을 6개만 써도 이런 커널에서 의미 있는 성능 향상을 얻을 수 있었습니다. 보조 커널이라면 튜닝과 유지 관리 오버헤드를 훨씬 낮춘 채 업스트림에 도입하는 또 다른 길이 생깁니다.
Fine-grained tuning, however, is not the only practical adoption strategy for Helion kernels. For smaller auxiliary kernels, such as quantization, activation, and normalization kernels, it can be preferable to trade some peak performance for a much smaller config set that generalizes across shapes. Our initial experiments show that meaningful performance improvements can be achieved for these kernels with as few as six configs. This provides another path toward upstream adoption with substantially lower tuning and maintenance overhead for auxiliary kernels.
관심 있는 사용자께서는 현재 구현을 사용해 보고 vLLM Helion 선형 백엔드 RFC에 경험을 공유해 주세요. 실제 배포 환경에서 얻은 피드백은 이 접근 방식들을 평가하고, 더 넓은 도입을 위한 통합 방향을 정하는 데 도움이 됩니다.
We encourage interested users to try the current implementation and share their experience in the vLLM Helion linear backend RFC. Feedback from real-world deployments will help us evaluate these approaches and guide the integration toward broader adoption.
향후 작업 / Future work
향후 작업은 여러 추론 워크로드와 하드웨어 플랫폼으로 Helion 커널의 적용 범위를 넓히는 데 집중합니다.
Future work will focus on expanding Helion kernel coverage across inference workloads and hardware platforms.
하드웨어 지원 범위(Hardware coverage). Helion 팀은 하드웨어 플랫폼 전반에서 백엔드 지원을 계속 확장하고 최적화하고 있습니다. 여기에는 NVIDIA Blackwell GPU용 CuteDSL 백엔드와, AMD GPU 및 TPU에 대해 진행 중인 성능 작업이 포함됩니다. 이 백엔드들이 성숙해지면 Helion 선형 백엔드를 이 하드웨어 타깃들로 확장하고 다시 평가할 계획입니다.
Hardware coverage. The Helion team is continuing to expand and optimize backend support across hardware platforms, including the CuteDSL backend for NVIDIA Blackwell GPUs and ongoing performance work for AMD GPUs and TPUs. As these backends mature, we plan to extend and re-evaluate the Helion linear backend across these hardware targets.
모델 지원 범위(Model coverage). 이번 작업은 선형 백엔드가 추론 지연 시간의 상당 부분을 차지하는 밀집 모델을 주로 대상으로 합니다. MoE 모델에서는 MoE 백엔드가 더 중요한 최적화 대상이 됩니다. 이런 워크로드에도 Helion의 커널 최적화 능력을 적용하고 모델 지원 범위를 넓히기 위해 Helion MoE 백엔드를 개발하고 있습니다.
Model coverage. This work primarily targets dense models, where the linear backend accounts for a significant portion of inference latency. For MoE models, the MoE backend becomes the more important optimization target. We are working on a Helion MoE backend to bring Helion’s kernel optimization capabilities to these workloads and broaden model coverage.
결론 / Conclusion
Helion의 고수준 추상화 덕분에 커널 구현 하나를 작성하고 유지 관리하면서, 서로 다른 워크로드와 하드웨어 타깃에 맞게 최적화할 수 있습니다. 이번 작업의 양자화 GEMM 커널이 보여 주듯, Standard GEMM, Split-K, Swap-AB 같은 알고리즘 변형조차 하나의 구현으로 통합해 자동 튜너가 고를 수 있는 튜닝 선택지로 노출할 수 있습니다. 형태별 세밀한 커널 튜닝과 하이브리드 디스패치를 결합한 Helion 선형 백엔드는, 평가한 모델 전반에서 Hopper GPU의 기본 백엔드인 CUTLASS, DeepGEMM, FlashInfer보다 좋은 성능을 냈습니다. 엔드투엔드 성능이 일관되게 향상되었고, 일부 워크로드에서는 처리량이 10% 넘게 개선되었습니다.
Helion’s high-level abstraction makes it possible to express and maintain a single kernel implementation while optimizing it across different workloads and hardware targets. As demonstrated by the quantized GEMM kernels in this work, even algorithmic variants such as Standard GEMM, Split-K, and Swap-AB can be unified into one implementation and exposed as tunable choices for the autotuner. Combined with per-shape fine-grained kernel tuning and hybrid dispatch, the Helion linear backend outperforms the default CUTLASS, DeepGEMM, and FlashInfer backends on Hopper GPUs across the evaluated models, delivering consistent end-to-end performance gains and throughput improvements exceeding 10% for some workloads.
하지만 이런 성능 향상에는 트레이드오프가 따릅니다. 지연 시간에 민감한 커널을 세밀하게 튜닝하면 성능은 좋아지지만 AOT 튜닝 노력이 늘어납니다. 미리 튜닝한 구성을 함께 배포하면 바로 쓸 수 있는 사용성은 좋아지지만 지속적인 유지 관리 비용이 듭니다. 이번 글 전체에서 다룬 성능-사용성-유지 관리성 트레이드오프가 여기서도 그대로 드러납니다.
These performance gains, however, come with tradeoffs. Fine-grained tuning for latency-critical kernels improves performance but increases AOT tuning effort, while shipping pre-tuned configs improves out-of-the-box usability at the cost of ongoing maintenance. This reflects the broader performance-usability-maintainability tradeoff discussed throughout this post.
현재는 vLLM 포크에 미리 튜닝한 구성을 함께 배포하고 있습니다. 업스트림 도입을 위해서는 다른 방식을 검토하고 있습니다. Helion 커널과 통합 프레임워크는 업스트림에서 유지 관리하고, 워크로드별 자동 튜닝은 최종 사용자에게 맡기는 방식입니다. 이 방식은 바로 쓸 수 있는 사용성보다 성능과 유지 관리성을 우선하지만, Helion의 자동화된 튜닝 프레임워크 덕분에 성능에 민감한 배포에서는 추가 최적화 단계가 현실적인 선택이 됩니다.
Today, we ship the pre-tuned configs with our vLLM fork. For upstream adoption, we are exploring a different model: maintain the Helion kernels and integration framework upstream while delegating workload-specific autotuning to end users. This favors performance and maintainability over out-of-the-box usability, but Helion’s automated tuning framework makes the additional optimization step practical for performance-sensitive deployments.
감사의 글 / Acknowledgments
이번 작업은 Red Hat의 OCTO 팀과 vLLM 팀, 그리고 Meta의 Helion 팀에 속한 많은 기여자의 도움을 받았습니다. 특히 작업 내내 피드백과 지원을 보내 준 동료 Richard Zou와 Jongsok Choi에게 감사드립니다.
This work was supported by many contributors across the OCTO and vLLM teams at Red Hat, as well as the Helion team at Meta. In particular, we would like to thank our colleagues: Richard Zou and Jongsok Choi for their feedback and support throughout this work.
덧글 작성 및 공유를 위해 https://pytorch.kr/blog/2026/building-a-high-performance-and-portable-vllm-linear-backend-with-helion/에 게시된 글이 커뮤니티에도 함께 게시되었습니다.